 AI & Machine Learning
A Shared Record Could Make AI Scores Easier to Compare
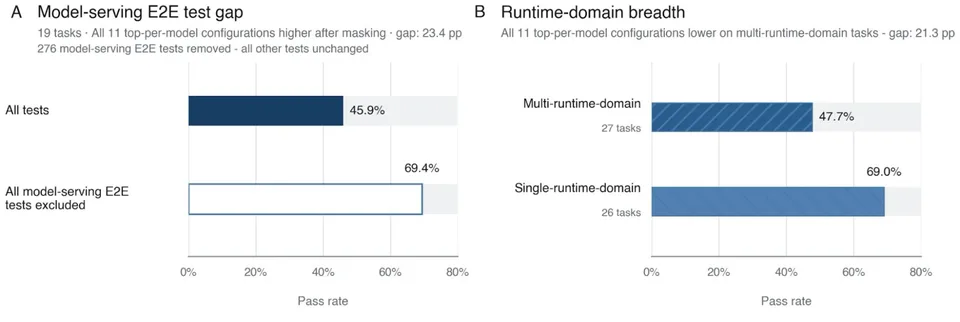
The UK AI Security Institute is publishing benchmark methods and setup details through EvalEval’s Evaluation Cards.
Alexander Cole ·
Machines. Intelligence. Everyday life.
NVIDIA’s runnable recipe groups expert calculations, uses 8-bit values, and fuses several operations; its benchmark reports up to 2.21× higher throughput on eight B200 GPUs.
Alexander Cole· · 5 min read
Read the story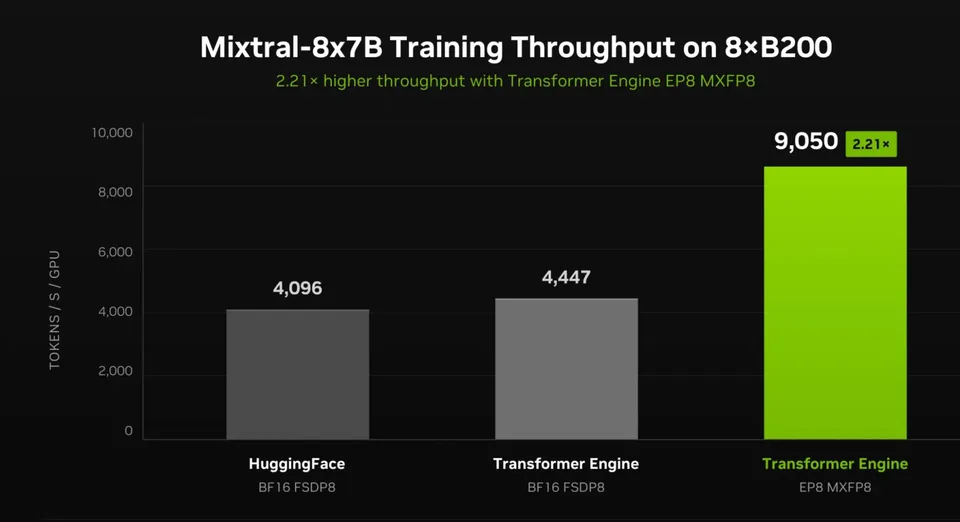
Image / developer.nvidia.com
AI & Machine LearningThe UK AI Security Institute is publishing benchmark methods and setup details through EvalEval’s Evaluation Cards.
Alexander Cole ·
 AI & Machine Learning
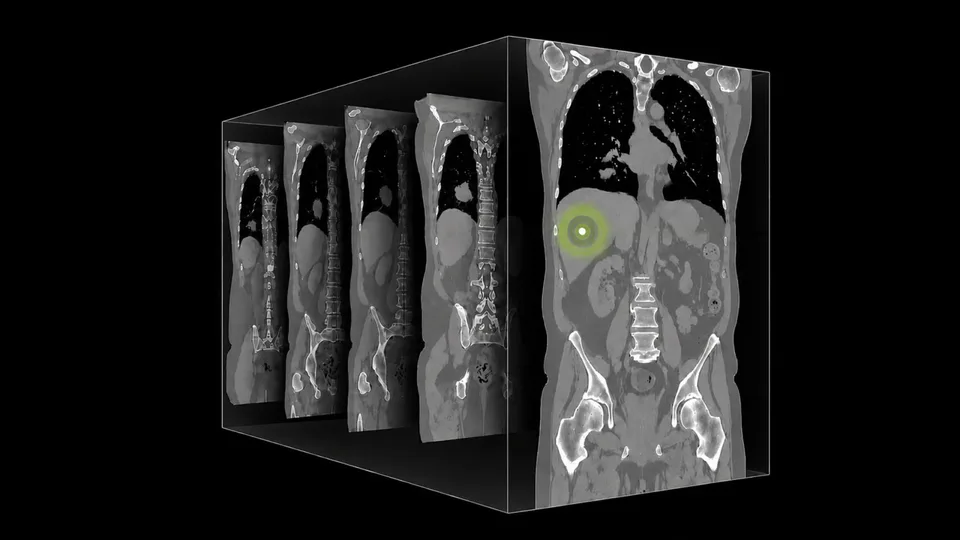
NVIDIA’s research model combines a full-volume view with radiologist-style training, but it is not cleared for patient diagnosis.
Alexander Cole ·
 Industrial Robotics
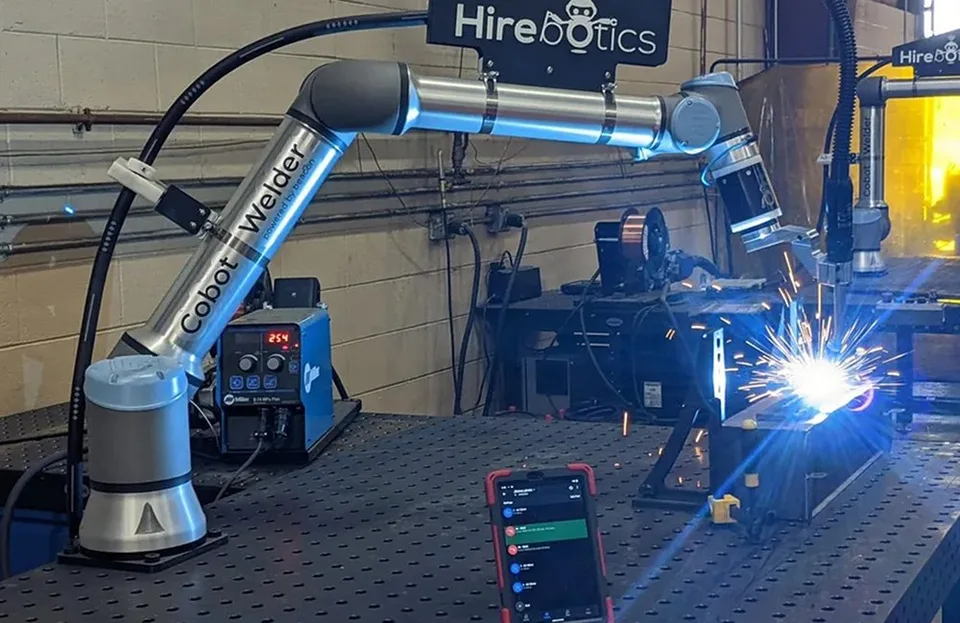
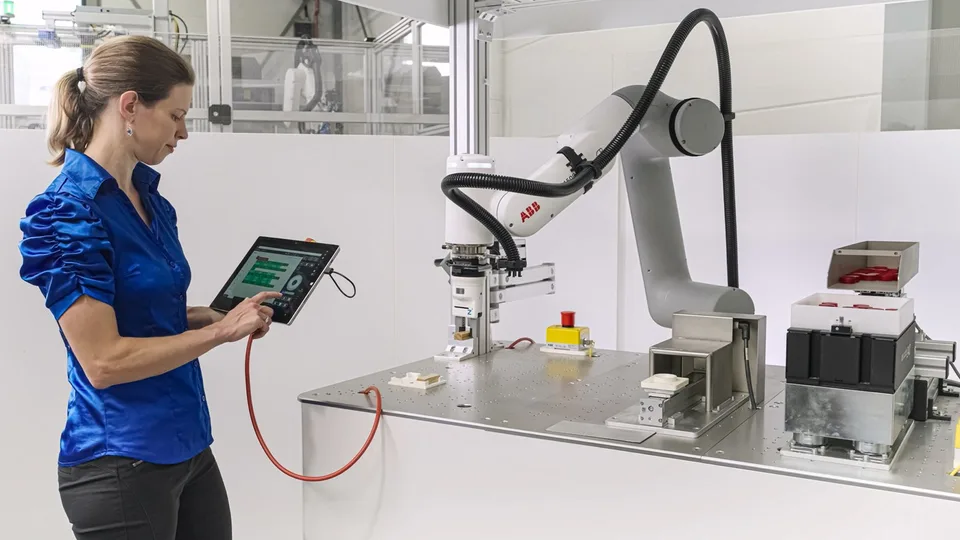
E-Device lets operators use a tablet or PC to program, simulate, monitor, and manually control compatible robots with physical safety controls.
Maxine Shaw ·
Different perspectives. One editorial standard.
Newsletter
The email briefing is not open for subscriptions yet. Follow our latest reporting through RSS.
Follow the live RSS feeds